| Product SKU | HGX-B300-8GPU |
|---|---|
| Form Factor | 8x NVIDIA Blackwell Ultra SXM |
| GPU | 8x NVIDIA B300 SXM |
| GPU Memory | 288 GB HBM3e per GPU |
| Total Memory | 2.1 TB HBM3e per 8-GPU baseboard |
| Memory Bandwidth | Up to 8 TB/s per GPU (up to 64 TB/s per node) |
| GPU Architecture | NVIDIA Blackwell Ultra |
| FP4 Tensor Core | 144 PFLOPS sparse / 108 PFLOPS dense |
| FP8/FP6 Tensor Core | 72 PFLOPS sparse / 36 PFLOPS dense |
| INT8 Tensor Core | 3 POPS sparse / 1.5 POPS dense |
| FP16/BF16 Tensor Core | 36 PFLOPS sparse / 18 PFLOPS dense |
| TF32 Tensor Core | 18 PFLOPS sparse / 9 PFLOPS dense |
| FP32 | 600 TFLOPS |
| FP64 / FP64 Tensor Core | 10 TFLOPS |
| NVIDIA NVLink | Fifth generation, 1.8 TB/s GPU-to-GPU, 14.4 TB/s total |
| NVIDIA NVLink Switch | NVLink 5 Switch |
| Networking | 8x NVIDIA ConnectX-8 SuperNICs, up to 800 Gb/s per GPU (2 x 400 Gb/s) |
| Networking Bandwidth | 1.6 TB/s |
| Attention Performance | 2x vs. HGX B200 |
| PCI Express | 8x Gen5 x16 and 1x Gen4 x2 per baseboard |
| Supported CPU Platform | Dual x86 CPU sockets, minimum 48 physical cores per socket (56 recommended), 2.0 GHz minimum base clock |
| System Memory | Minimum 2 TB per node, minimum 500 GB/s bandwidth |
| DPU | 1x NVIDIA BlueField-3 DPU per server (north/south) |
| Local Storage | 1-2 TB NVMe per CPU socket plus 1 TB NVMe boot drive (NVIDIA Enterprise RA recommendation) |
| Cooling | Air-cooled or direct-to-chip liquid, per OEM system design |
| Security | TPM 2.0 module (secure boot) |
| System Management | SMBPBI over SMBus (OOB) to BMC, PLDM T5-enabled, SPDM-enabled |
| Target Workloads | Large language models, traditional deep learning inference, HPC |
| NVIDIA AI Enterprise | Add-on |
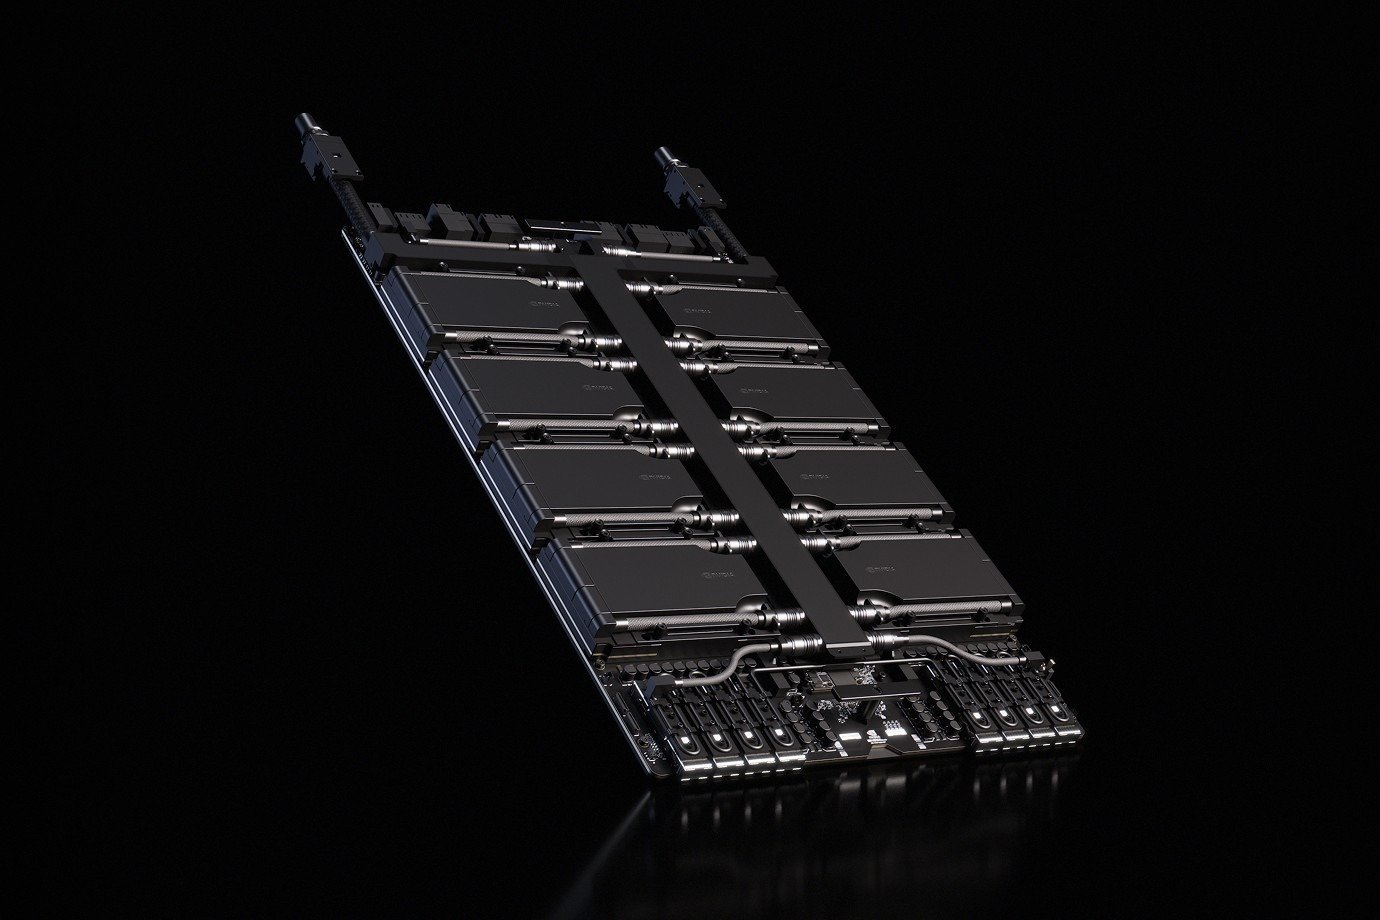
NVIDIA HGX B300 8-GPU Baseboard
The NVIDIA HGX B300 8-GPU Baseboard is the Blackwell Ultra platform for AI data centers, carrying eight NVIDIA B300 SXM GPUs with 288 GB of HBM3e each, up to 2.1 TB per baseboard. It combines up to 144 PFLOPS of FP4 Tensor Core performance (108 PFLOPS dense) with 1.8 TB/s of GPU-to-GPU bandwidth over fifth-generation NVLink and NVSwitch, and integrates eight NVIDIA ConnectX-8 SuperNICs at up to 800 Gb/s per GPU for scale-out networking.
Overview
The NVIDIA HGX B300 8-GPU Baseboard is the Blackwell Ultra platform behind every NVIDIA-Certified B300 server that is not a DGX system. It integrates eight NVIDIA B300 SXM GPUs on a single baseboard, connected by fifth-generation NVLink and NVSwitch at 1.8 TB/s of GPU-to-GPU bandwidth and 14.4 TB/s of aggregate NVLink bandwidth. Total GPU memory reaches 2.1 TB of HBM3e — 288 GB per GPU, a 60% increase over the 180 GB of HGX B200 per GPU. Scale-out networking is built into the platform itself: eight NVIDIA ConnectX-8 SuperNICs provide up to 800 Gb/s per GPU (2 × 400 Gb/s), so the NIC choice is no longer left to the OEM. OEMs including Supermicro, Dell, HPE and Lenovo wrap their own CPUs, chassis and cooling around the baseboard to build air-cooled 8U or direct-liquid 4U/2-OU systems.
Key Features
- Eight NVIDIA B300 SXM GPUs: Blackwell Ultra compute with up to 144 PFLOPS of FP4 Tensor Core performance (108 PFLOPS dense) per baseboard.
- 288 GB HBM3e per GPU: 2.1 TB of total GPU memory per baseboard and up to 8 TB/s of bandwidth per GPU — the memory capacity that long-context and mixture-of-experts inference depends on.
- Fifth-generation NVLink and NVSwitch: 1.8 TB/s of GPU-to-GPU bandwidth and 14.4 TB/s of aggregate NVLink bandwidth across all eight GPUs, with a full any-to-any switch fabric.
- On-platform scale-out networking: Eight NVIDIA ConnectX-8 SuperNICs at up to 800 Gb/s per GPU (2 × 400 Gb/s), with 1.6 TB/s of networking bandwidth per baseboard — double that of HGX B200.
- About 2x attention throughput: Roughly double the attention-layer performance of HGX B200, which is what lifts token throughput for reasoning and agentic AI serving.
- FP64 note: FP64 and FP64 Tensor Core run at 10 TFLOPS per baseboard, against 296 TFLOPS on HGX B200 — B300 is tuned for FP4/FP8 AI workloads rather than double-precision HPC.
Applications
- Large-scale reasoning and agentic AI inference and serving
- Mixture-of-experts and long-context model pretraining and fine-tuning
- AI factory and token-factory deployments
- Accelerated data analytics and AI-adjacent HPC workloads
Configuration, availability and lead time depend on the required quantity, chassis and CPU platform, and delivery destination. Send your requirement to receive a quotation.